Part Of: [Advanced Inference In Graphical Models] sequence
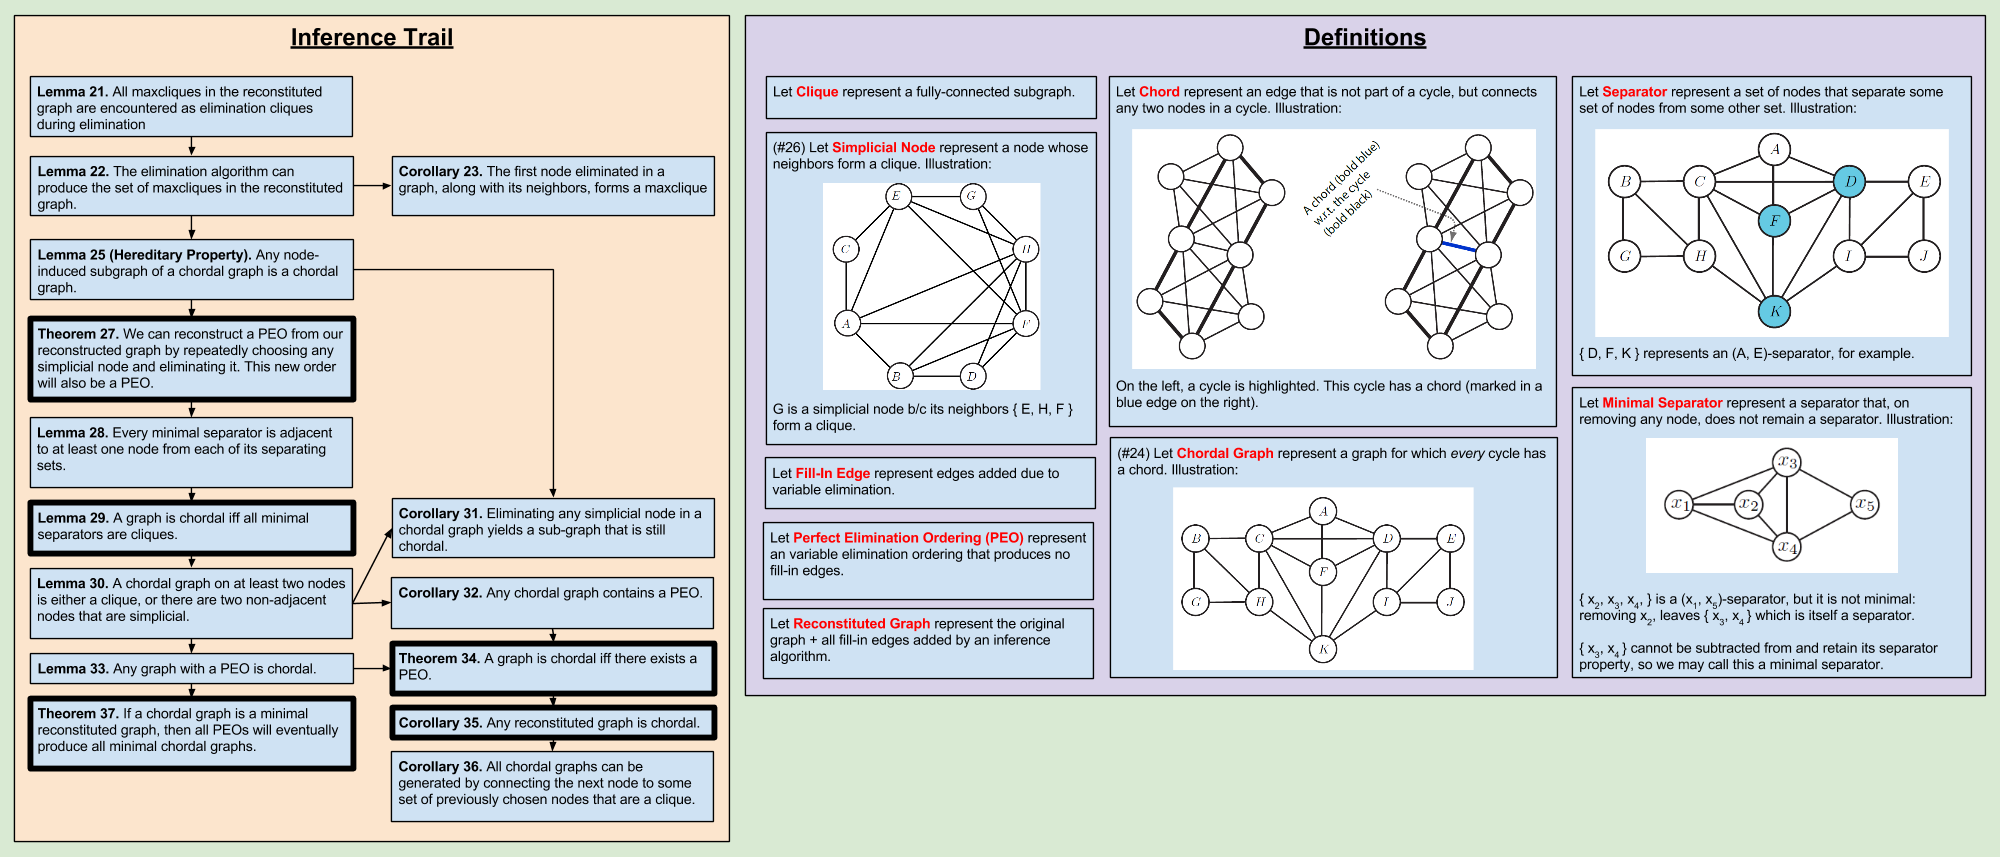
I made this infographic while studying the relationship between chordal graphs and perfect elimination orderings.
Results I found particularly useful have their edges bolded. Enjoy!
Part Of: [Advanced Inference In Graphical Models] sequence
I made this infographic while studying the relationship between chordal graphs and perfect elimination orderings.
Results I found particularly useful have their edges bolded. Enjoy!
Part Of: [Advanced Inference In Graphical Models] sequence
Followup To: [Murderous Cliques]
Table Of Contents
Context
Our takeaways from last time:
We can make our conclusion more specific.
Let perfect elimination ordering refer to exact inference algorithms that do not at any step introduce fill-in edges; F = {}.
In order to accomplish such an ordering, we should eliminate nodes that match either one of two elimination principles:
In either case, fill-in edges will not be added because the clique requirement is already satisfied.
Forests & Trees
So far in this sequence, we have considered a wide variety of different graph types. Today, let us consider a special type of graph: the forest, and the tree.
Informally, a forest is a graph that has no cycles. A tree is a connected forest, a forest in which two nodes are connected by precisely one path.
Below is one forest comprising four trees:

Theorem 2 (Trees, Berge). Let T = (V, E) be an undirected graph with |V| = n > 2. Then each of the following properties are equivalent and each can be used to define a tree.
Perfect Elimination
Do all graphs support a perfect elimination ordering (PEO)? Consider the following:

In the left image, a PEO does not exist: it doesn’t matter which node you chose, its two neighbors are not already-connected. The right image, in contrast, does contain a PEO (as was shown last time).
Notice how the left 4-cycle is not a tree, whereas the right chain is. Might other types of trees (besides chains) also support perfect elimination orderings? The answer turns out to be yes:
Therefore, any leaf-first ordering on a tree will yield a perfect elimination order, and operate in O(N*r^2) time.
Two important facts to remember:
Murderous Messages
Time to view leaf-first ordering in action. Consider a tree T with |V| = 15. Suppose that, after building this tree with statistical data, a scientist submits a query as to the relationship between two variables.
We know how to perform this inference: eliminate all variables not involved in the query itself. To perform such elimination perfectly, we perform leaf-first ordering:

In the right image, we “rooted” T on the query variables, and eliminated the irrelevant nodes starting from the “lowest” ones.
Pay attention to the way information flows with the above ordering. It is as if the query variables act as a collecting magnet, sucking information from the rest of the graph towards its nodes. On a Bayesian interpretation of this algorithm, we can meaningfully state that this leaf-first ordering is a collection of evidence. Let us call such transmission of evidence message passing.
We can then re-interpret leaf-first ordering in the following protocol:
Message Passing Protocol (MPP): A message may be sent from node i to a neighbor node j only after node i has received a message from all of its other neighbors.
We motivated the MPP based on trees, and elimination principle #1. But we will later MPP in the context of chordal graphs, which guarantee principle #2.
Two things to bear in mind as we close:
Takeaways
Part Of: [Advanced Inference In Graphical Models] sequence
Table Of Contents
Cliquish Nodes
Fully-connected networks have some interesting properties. Let’s create a vocabulary to reason about them in more nuanced graphs.
An example may help, you say?!
 Our three sets in action:
The Mechanics Of Variable Elimination
The basic point of variable elimination is to push summation signs as far to the right as possible, to reduce computational complexity (you no longer have to ask factors not involving xi, to sum over it).
Let us call this the factor grouping step:
 See how we pulled xi summation to the right?
Once we have a single summation over only the relevant factors, we proceed. The resultant aggregation will no longer contain Xi; therefore, let us call this operation variable elimination step.

To be clear, the above notation is a psi1, 2 – but the one is scratched out, to represent its elimination.
Putting these two steps together, we can now understand the process of eliminate a variable from our model. Consider the task of eliminating x1 from the following model:

The above image captures the process for eliminating one variable. To find p(x3, x4), we must eliminate two more. Imagine we choose X5 to eliminate next, and then X2. The resulting equation will bear our answer, the value of p(x3, x4).
A Question Of Order
In the above example, we chose the following variable elimination ordering: (1, 5, 2). But other orderings are possible. How does (1, 5, 2) compare to (2, 1, 5) or (5, 2, 1)?
How might we rank the desirability of different variable elimination orderings? An attractive metric is computational complexity: we should choose the ordering that minimizes the amount of required CPU muscle.
Enter Graphical Models
Graphical models provides us a way to visually inspect what used to be solely manipulations of formulae. Here is the exact same computation as above, but with pictures:

The key insight: the reconstituted graphical model (GM) is equivalent to the original GM.
HOWEVER! Such equivalence is not guaranteed! Consider what happens when we eliminate X4 first:

Notice how the reconstituted GM diverges from the original GM: a new edge has been added between x3 and x5. Let us call this a fill-in edge.
Fill-in edges are bad news. The edges of the original graph constitute its family: when you add edges, the boundaries of the family expands, which hurts inference processes. Recasting our lens to asymptotic analysis, fill-in edges represent an added computational burden – tables whose dimensionality we would rather not compute over.
Why does choosing to first eliminate X4 create a fill-in edge? To understand these, we’ll need to apply deep mathematics to analyze relationships between different families F(G, R).
Murderous Cliques
Let us use MRF-clique semantic interchangeability to look at fill-in edges with the lens of clique semantics. Consider again the fill-in edge phenomenon encountered above:

In the original graph (left), the maximal cliques are {{1, 2}, {2, 3}, {3, 4}, {4, 5}}. The key insight is as follows:
In other words:
We can explain the x4 fill-in edge because its neighbors (x3 and x5) were not already a clique.
Thus, variable elimination ordering becomes a question of analyzing the cliques of a graph. Let us call this perspective murderous cliques for short! 🙂
Takeaways
Part Of: [Advanced Inference In Graphical Models] sequence
Table Of Contents
Definitions Make The World Go ‘Round
Agents within the particle soup of the universe may sample its contents.
Searching The Universe
How big is U? Well, let’s imagine a simple case, where N = 3, and the domain of every random variable is {true, false}.

Two things to notice in the above joint probability table:
The Topography Of Truth
Our probability function must generate a value for every permutation of random variable values. Using the |*| notation to represent a “size/number of” operator, we find that |rows| = |domain|^|variables|. This equation explains why we have eight rows: 8 = 2^3.
But what happens when N is larger than 3? For any N, the number of rows we must use to provide p(X1, …, XN) is 2^N. But exponential growth is not computationally tractable. Intractability means that any computational system – brain or CPU – cannot hope to traverse U efficiently.
The above line of reasoning is called asymptotic analysis. But there exists another way to reason about tractability.
Imagine there exists a distribution ptrue(x1, …, xN) that our search algorithm tries to locate within U. But ptrue(x1, …, xN) is just one distribution out of many. We can represent the situation with a solution landscape:
In our solution landscape, ptrue(x1, …, xN) is simply the highest peak in the landscape, and our search algorithms’ task is simply to locate it. We can call this process gradient ascent.
Tractable landscapes tend to be convex, with no local minima; therefore, gradient ascent will lead to the ptrue(x1, …, xN) peak. Intractable landscapes tend to be, well… more chaotic.

In such unforgiving terrain, it becomes clear why searching U, even via sophisticated approximation algorithms, tends to yield inadequate solutions.
Redemption Via Solution-Space Constraint
Let a graph comprise a set of vertices V, and a set of edges E. A graphical model, then, is the conjunction of a graph with a set of rules R. More formally:
What type of rules comprise R? I discuss cognitive versions of such rules here.
R are a set of rules that map from graph G to statements about probability distributions. An individual rule r is a predicate (truth statement) that takes a graph and a probability distriution, and evaluates to either true or false.
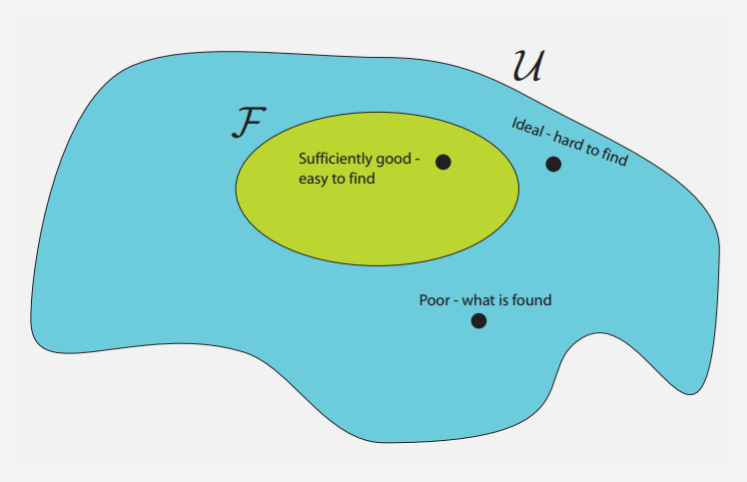
In practice, the rules in R tend to encode conditional independence. The important point, though, is that R constrains U. The set of probability distributions that conform to the rules of some graphic model is smaller than the set of all possible distributions. Let F represent a family of distributions, a subset of all possible distributions U.
More importantly, the rules of a graphical model are carefully designed to yield a tractable family of the solution space. Thus, solution space looks like:
To paraphrase my professor:
Sometimes it’s better to find an exact solution to an approximate problem [exact inference on F] than to find an approximate solution to an exact problem [approximate inference on U].
Hi! So, I’m trying out something new. It’s no longer summer, which means I have much less time to follow my own research paths (because class). But this quarter, I want to “live blog” my insights as I go along. The class is:
Lecture Posts
Exact Inference On Approximate Problem:
Approximate Inference on Exact Problems:
Final Project Posts
Part Of: Breakdown of Will sequence
Followup To: Rule Feedback Loops
Content Summary: 1300 words, 13 min read
Context
Here’s where we landed last time:
Today’s post will draw from the following:
Time to connect these threads! 🙂 Let’s ground our warfare narrative in the formal systems of game theory.
Schizophrenic’s Dilemma
First, we interpret { larger-later (LL) vs. smaller-sooner (SS) } rewards in terms of { cooperation vs. defection } decisions.
Second, we name our actors:
Does this game suffer from the same issue as classical PD? Only one way to find out!

Here’s how I would explain what’s going on:
Take some time to really ingest this diagram.
Iterated Schizophrenic’s Dilemma (ISD)
Okay, so we now understand how to model intertemporal warfare as a kind of “Schizophrenic’s Dilemma“. But we “have to live with ourselves” — the analogy ought to be extended across more than one decision. Here’s how:
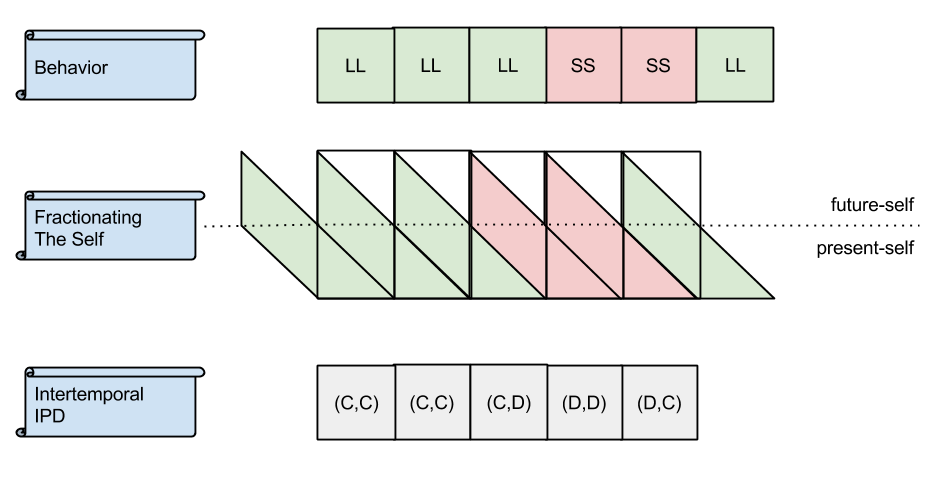
Time flows from left to right. In the first row, we see that an organism’s choices are essentially linear. For each choice, the reasoner selects either an LL (larger-longer) or an SS (smaller-sooner) reward. How can this be made into a two-dimensional game? We can achieve this graphically by “stretching each choice point up and to the left”. This move ultimately implements the following:
It is by virtue of this rule that we are able to conceptualize the present-self competing against the future-self (second row). The third row simply compresses the second into one state-space.
Let us call this version of the Iterated Prisoner’s Dilemma, the Iterated Schizophrenic’s Dilemma. For the remainder of this article, I will use IPD and ISD to distinguish between the two.
The Lens Of State-Space
We have previously considered decision-space, and outcome-space. Now we shall add a third space, what I shall simply call state-space (very similar to Markov Decision Processes…)

You’ll notice that the above state-space is a fully-connected graph: in IPD, any decision can be made at any time.
But this is not true in ISD, which must honor the rule of Temporal Continuity. For example, (C, C) -> (D, C) violates that “the future-self of one time step must be equivalent to the present-self of the next time step”. The ISD State-Space results from trimming all transitions that violate Temporal Continuity:
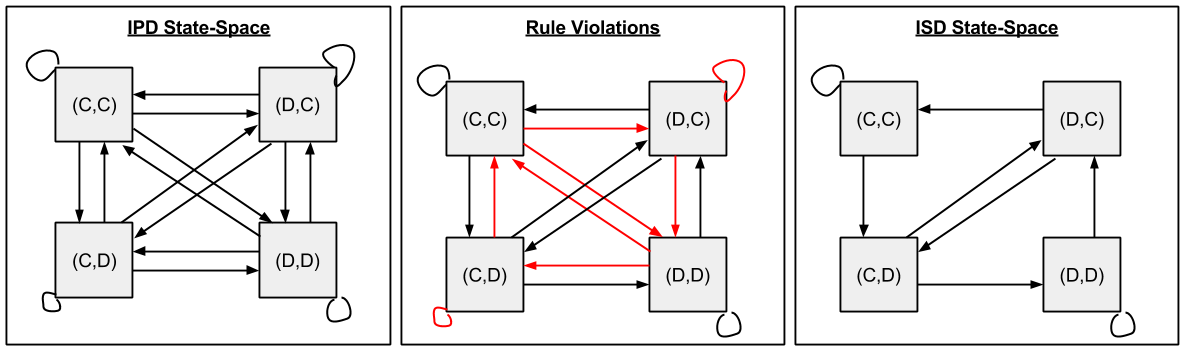
Let me briefly direct your attention to three interesting facts:
Intertemporal Retaliation
Four qualities of successful IPD strategies are: nice, forgiving, non-envious, and retaliating. How does retaliation work in the “normal” IPD?
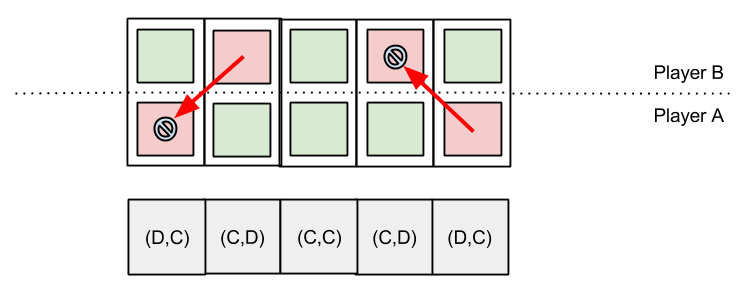
Here we have two cases of retaliation:
Note the easy two-way symmetry. But in the ISD case, the question of retaliation becomes very complex:
What, then, is to motivate our present-selves to “keep the faith”? To answer this, we need only appeal to the feedback nature of personal rules (explored last time)!
I’ll let Ainslie explain:
As Bratman has correctly argued (Bratman 1999, pp. 35-57), a present “person-stage” can’t retaliate against the defection of a prior one, a difference that disqualifies the prisoner’s dilemma in its classical form as a rationale for consistency. However, insofar as a failure to cooperate will induce future failures, a current decision-maker contemplating defection faces a danger of the same kind as retaliation…
With the question of retaliation repaired, the analogy between IPD and ISD seems secure. Ainslie has earned the right to invoke IPD explananda; for example:
The rules of this market are the internal equivalent of “self-enforcing contracts” made by traders who will be dealing with each other repeatedly, contracts that let them do business on the strength of handshakes (Klein & Leffler 1981; Macaulay 1963).
Survival Of The Salient
After casting warfare of successive selves into game theoretic terms, we are in a position to import other concepts. Consider the Schelling point, the notion that salient choices function as an attractor between competitors. Here’s an example of the Schelling point:
Consider a simple example: two people unable to communicate with each other are each shown a panel of four squares and asked to select one; if and only if they both select the same one, they will each receive a prize.Three of the squares are blue and one is red. Assuming they each know nothing about the other player, but that they each do want to win the prize, then they will, reasonably, both choose the red square. Of course, thered square is not in a sense a better square; they could win by both choosing any square. And it is only the “right” square to select if a player can be sure that the other player has selected it; but by hypothesis neither can. However, it is the most salient and notable square, so—lacking any other one—most people will choose it, and this will in fact (often) work.
By virtue of the feedback mechanism discussed above, rules are adapt over time via a kind of variation on natural selection (“survival of the salient“):
Intertemporal cooperation is most threatened by rationalizations that permit exceptions for the choice at hand, and is most stabilized by finding bright lines to serve as criteria for what constitutes cooperation. A personal rule never to drink alcohol, for instance, is more stable than a rule to have only two drinks a day, because the line between some drinking and no drinking is unique (bright), while the two-drinks rule does not stand out from some other number, or define the size of the drinks, and is thus susceptible to reformulation. However, skill at intertemporal bargaining will let you attain more flexibility by using lines that are less bright. This skill is apt to be a key component of the control processes that get called ego functions.
In the vocabulary of our model, it is the peculiarities of the preference bundling module whereby Schelling points are more effectual.
Let us close by, in passing, noting that this line of argument can be generalized into a justification for slippery slope arguments.
Takeaways
Part Of: Breakdown of Will sequence
Followup To: Willpower As Preference Bundling
Content Summary: 900 words, 9 min reading time
Context
When “in the moment”, humans are susceptible to bad choices. Last time, we introduced willpower as a powerful solution to such akrasia. More specifically:
But this only explained how preference bundling works at the level of utility curves. Today, we will learn how preference bundling is mentally implemented, and this mental model will in turn provide us with predictive power.
Building Mental Models
Time to construct a model! 🙂 You ready?!
In our last post, we discussed three distinct phases that occur during preference bundling. We can then imagine three separate modules (think: software programs) that implement these phases.
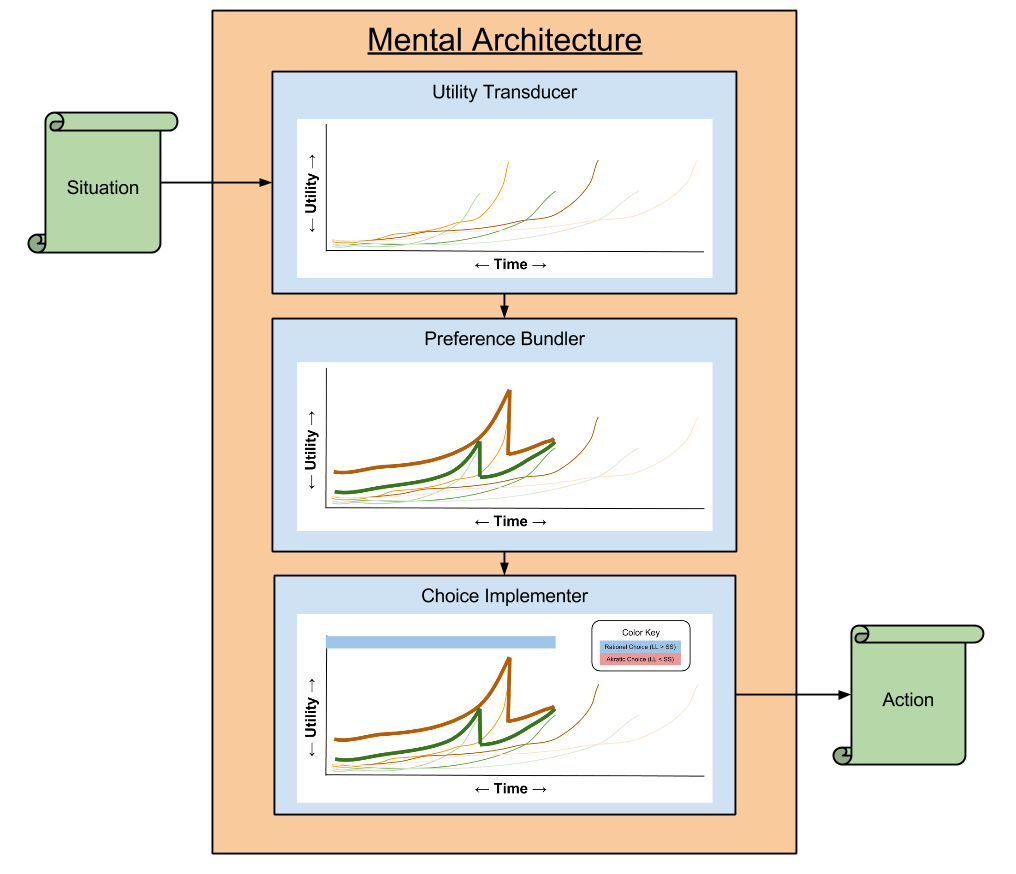
This diagram provides a high-level, functional account of how our minds make decisions. The three modules can be summarized as follows:
The above diagram is, of course, merely a germinating seed of a more precise mental architecture (it turns out that mind-space is rather complex 🙂 ). Let us now refine our account of the Preference Bundler.
Personal Rules
Consider what it means for a brain to implement preference bundling. Your brain must receive utility-anticipated information from an arbitrary number of choice valuations, and aggregate similar decisions into a single measure.
Obviously, the mathematics of such a computation lies underneath your awareness (your superpower is math). However, does the process entirely fail to register in the small room of consciousness?
This seems unlikely, given the common phenomenal experience of personal rules. Is it not likely that the conscious experience of “I will never stay up past midnight on a weeknight” does not in some way correlate with the actions of the Preference Bundler?
Let’s generalize this question a bit. In the context of personal rules, we are inquiring about the meaning of quale-module links. This type of question is relevant in many other contexts as well. It seems to me that such links can be roughly modeled in the vocabulary of dual-process theory, where System 1 (parallel modules) data bubbles up into System 2 (sequential introspection) experience.
Let us now assume that the quale of personal rules correlates to some variety of mental substance. What would that substance have to include?
In terms of complexity analysis, it seems to me that a Preference Bundler need not generate relevant rules on the fly. Instead, it could more efficiently rely on a form of rule database, which tracks a set of rules proven useful in the past. Our mental architecture, then, looks something like this (quales are in pink):

In his book, Ainslee presents intruging connections between this idea of a rule database with similar notions in the history of ideas:
The bundling phenomenon implies that you will serve your long-range interest if you obey a personal rule to behave alike towards all members of a category. This is the equivalent of Kant’s categorical imperative, and echoes the psychologist Lawrence Kohlberg’s sixth and highest principle of moral reasoning, deciding according to principle. It also explained how people with fundamentally hyperbolic discount curves may sometimes learn to choose as if their curves were exponential.
Recursive Feedback Loops
Personal rules, of course, are not spontaneously appear within your mind. They are constructed by cognitive processes. Let us again expand our model to capture this nuance:

Describing our new components:
A feedback loop exists in our mental model. Observe:
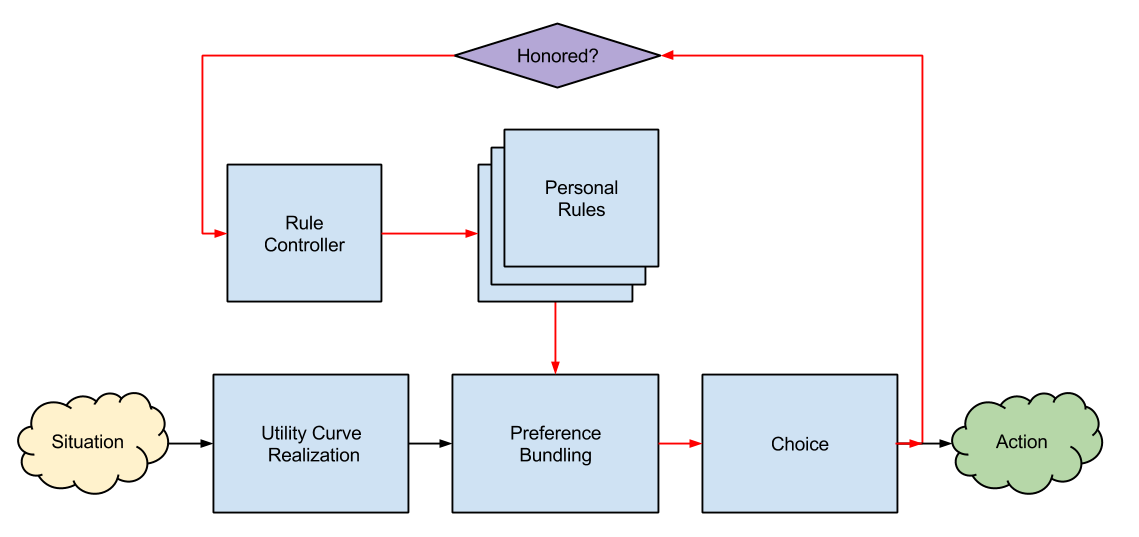
Feedback loops can explain a host of strange behavior. Ainslie describes the torment of a dieter:
Even if [a food-conscious person] figures, from the perspective of distance, that dieting is better, her long-range perspective will be useless to her unless she can avoid making too many rationalizations. Her diet will succeed only insofar as she thinks that each act of compliance will be both necessary and effective – that is, that she can’t get away with cheating, and that her current compliance will give her enough reason not to cheat subsequently. The more she is doubtful of success, the more likely it will be that a single violation will make her lose this expectation and wreck her diet. Personal rules are a recursive mechanism; they continually take their own pulse, and if they feel it falter, that very fact will cause further faltering.
Takeaways
And that’s a wrap! 🙂 I am hoping to walk away from this article with two concepts firmly installed:
Next Up: [Iterated Schizophrenic’s Dilemma]
Part Of: [Breakdown of Will] sequence
Followup To: [An Introduction To Hyperbolic Discounting]
Table Of Content
Motivations
Consider again the takeaways from our preceding post:
With this model of akrasia in hand, we will proceed to explore: akrasia therapies, tactical countermeasures we employ to combat your “sin nature”.
How do people verbalize their struggle to preserve “perspective from a distance”? Well, excepting cases where their past selves deprive their future selves of freedom (think of Odysseus chaining himself to the ship), more often than not people gesture towards the concept of willpower.
Today we will build an account of what this fuzzy word actually means.
Choice Is Not A Snapshot
Do you remember our cartoon of a hyperbolic discount curve? Here it is again:

Recall that the orange curge is LL (the larger-later reward), and the green in SS (the smaller-sooner reward). Akrasia occurs when some temptation transiently overpowers the choice we would otherwise select (when SS > LL).
Now this picture is, of course, extremely narrow. We haven’t discussed:
I hope to get to these questions eventually. Today, I’d like to introduce just one “complication” into our cartoon: in real life, an organism must confront many choices across its lifespan.

Utility Anticipation
Imagine your author waging an war-with-himself re: whether to stay up late researching, or get a full night’s sleep. Does the above graph comfortably fit in this category of recurrent choice?
One could argue that it fails: there is nothing to stop me from weighing the choices of my one-week-from-now self. To do this, I must represent their utilities in the present. Here’s how we might support such utility anticipation (only three examples shown, to constrain complexity):

Does this anticipation counteract akrasia, instances where LL (larger-later reward) loses to SS (small-sooner reward)? To answer this, simply compare the utility curves:

Akratic lapses persist. But if utility anticipation is not the root of willpower, what is?
Preference Bundling
Our innovation has its roots in philosophy.
Writers since antiquity have recommended that impulses could be controlled by deciding according to principle, that is, deciding in categories containing a number of choices rather than just the choice at hand. Aristtotle said that akrasia is the result of choosing according to “particulars” instead of “universals”. Kant said that the highest kind of decision-making involves making all choices as if they defined universal rules (the “categorical imperative”)… this also echoes the psychologist Lawrence Kohlberg’s sixth and highest principle of moral reasoning, deciding according to principle.
Imagine, for a moment, if we were to sum these utility curves together. Three time-slices should illustrate how this summing works:
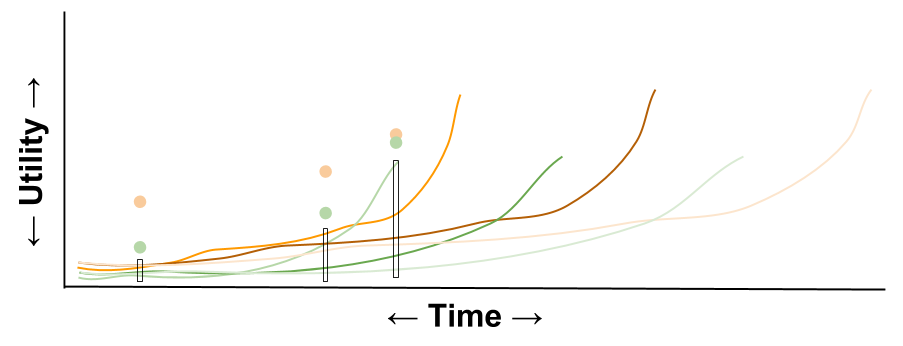
Consider the middle time slice (middle rectangle). If you look closely, you’ll see it intersect three orange LL functions and the three green SS functions. If we sum the three LL values together, we arrive at a single (larger) LL value. Same story goes for the three green SS lines. The two circles directly over the rectangle represent these two sums.
In the above illustration, we bundled preferences at three particular times. But what is to stop us from doing the same computation at all times? Nothing, and after we do this, we obtain new utility lines. These lines represent the bundled utility curves of all three choices.
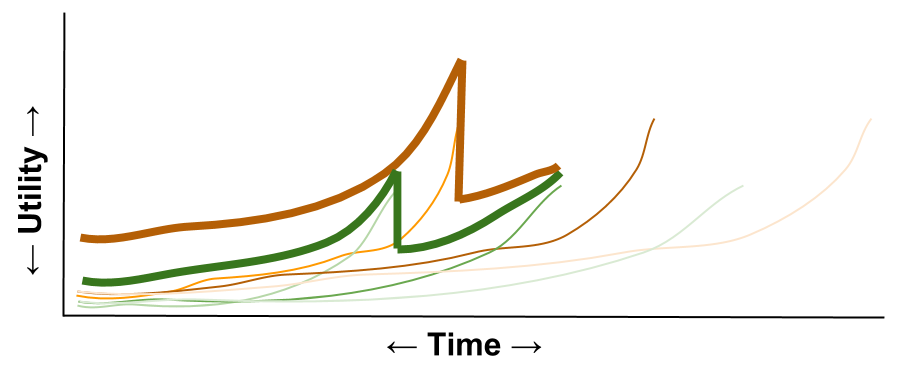
(Why don’t we continue this addition for the entire displayed x-axis? Well, to preserve the effect, after Choice1 expires, you have to take into account Choice4, etc etc…)
Casting these bundled utility curves back to the language of successive selves:

In this situation, then, we see the defeat of akrasia – the victory of willpower!
Takeaways
Next Up: [Personal Rule Feedback Loops]
In this sequence, we will be exploring this précis of this book. Specifically, we will be exploring the implications of akrasia (the act of behaving against one’s own desires).
Preliminary Posts
Content Summary
Part Of: [Breakdown of Will] sequence
Table Of Contents
What Is Akrasia?
Do you agree or disagree with the following?
In a prosperous society, most misery is self-inflicted. We smoke, eat and drink to excess, and become addicted to drugs, gambling, credit card abuse, destructive emotional relationships, and simple procrastination, usually while attempting not to do so.
It would seem that behavior contradicting one’s own desires is, at least, a frustratingly common human experience. Aristotle called this kind of experience akrasia. Here’s the apostle Paul’s description:
I do not understand what I do. For what I want to do I do not do, but what I hate I do. (Romans 7:15)
The phenomenon of akrasia, and the entire subject of willpower generally, is controversial (a biasing attractor). Nevertheless, both its description and underlying mechanisms are empirically tractable. Let us now proceed to help Paul understand, from a cognitive perspective, the contradictions emerging from his brain.
We begin our journey with the economic concept of utility.
Utility Curves, In 200 Words Or Less!
Let utility here represent the strength with which a person desires a thing. This value may change over time. A utility curve, then, simply charts the relationship between utility and time. For example:

Let’s zoom in on this toy example, and name three temporal locations:
Consider the case when NOW = tbeginning. At that time, we see that the choice is valued at 5 “utils”.

Consider what happens as the knife edge of the present (the red line) advances. At NOW = tmiddle, the utility of the choice (the strength of our preference for it) doubles:
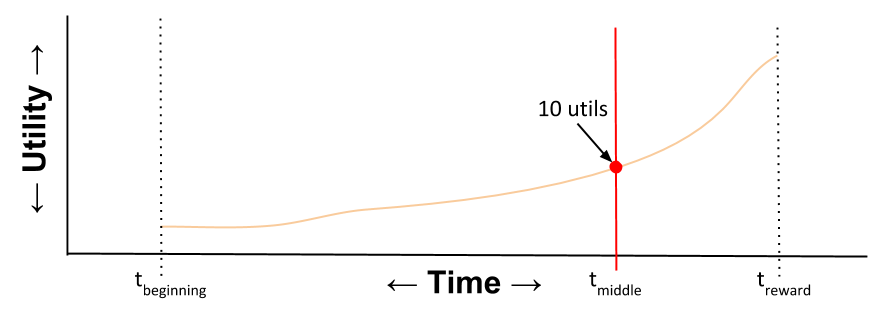
Increasing utility curves also go by the name discounted utility, which stems from a different view of the x-axis (at the decision point looking towards the past, or setting x to be in units of time delay). Discounted utility reflect something of human psychology: given a fixed reward, other things equal, receiving it more quickly is more valuable.
This concludes our extremely complicated foray into economic theory. 😛 As you’ll see, utility curves present a nice canvas on which we can paint human decision-making.
Choosing Marshmallows
Everyday instances of akrasia tend to be rather involved. Consider the decision to maintain destructive emotional relationships: the underlying causal graph is rather difficult to parse.
Let’s simplify. Ever heard of the Stanford Marshmallow Experiment?
In these studies, a child was offered a choice between one small reward (sometimes a marshmallow) provided immediately or two small rewards if he or she waited until the tester returned (after an absence of approximately 15 minutes). In follow-up studies, the researchers found that children who were able to wait longer for the preferred rewards tended to have better life outcomes, as measured by SAT scores, educational attainment, body mass index (BMI) and other life measures.
Naming the alternatives:
Marshmallows are simply a playful vehicle to transport concepts. Why are we tempted to reach for SS despite knowing our long-term interests lie with LL?
Here’s one representation of the above experiment (LL is the orange curve, SS is green):
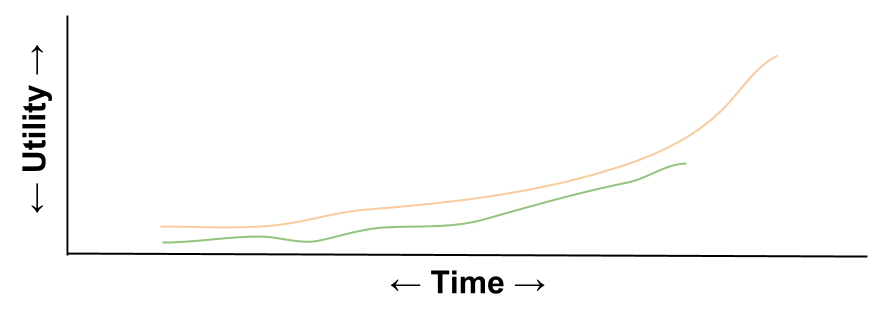
Our definition of utility was very simple: a measure of preference strength. This article’s model of choice will be equally straightforward: humans always select the choice with higher utility.
The option will people select? Always the orange curve. No matter how far the knife edge of the present advances, the utility of LL always exceeds that of SS:

Shockingly, economists like to model utility curves like these with mathematical formulas, rather than Google Drawings. These utility relationships can be produced with exponential functions; let us call them exponential discount curves.
Devil In The (Hyperbolic) Details
But the above utility curves are not the only one that could be implemented in the brain. Even if we held Utility(tbeginning) and Utility(treward) constant, the rate at which Utility(NOW) increases may vary. Consider what happens when most of the utility obtains close to reward-time (when the utility curves form a “hockey stick”):
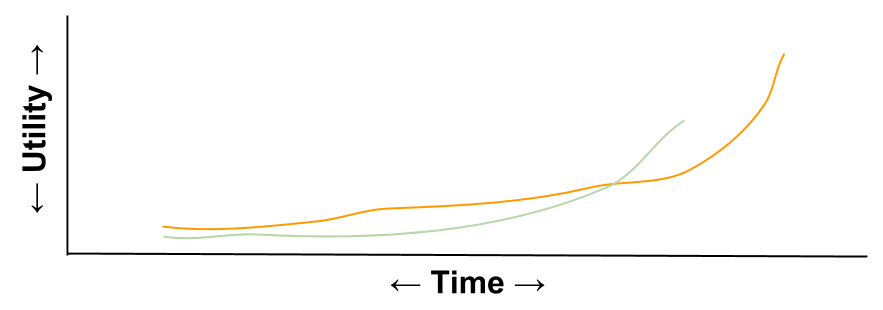
Let us quickly ground this alternative in a mathematical formalism. A function that fits our “hockey stick” criteria is the hyperbolic function; so we will name the above a hyperbolic discount curve.
Notice that the above “overlap” is highly significant – it indicates different choices at different times:

This is the birthplace of akrasia – the cradle of “sin nature” – where SS (smaller-sooner) rewards temporarily outweigh LL (larger-later) rewards.
The Self As A Population
Consider the story of Odysseus and the sirens:
Odysseus was curious as to what the Sirens sang to him, and so, on the advice of Circe, he had all of his sailors plug their ears with beeswax and tie him to the mast. He ordered his men to leave him tied tightly to the mast, no matter how much he would beg. When he heard their beautiful song, he ordered the sailors to untie him but they bound him tighter.
With this powerful illustration of akrasia, we are tempted to view Odysseus as two separate people. Pre-siren Odysseus is intent on sailing past the sirens, but post-siren Odysseus is desperate to approach them. We even see pre-siren Odysseus restricting the freedoms of post-siren Odysseus…
How can identity be divided against itself? This becomes possible if we are, in part, the sum of our preferences. I am me because my utility for composing this article exceeds my utility attached to watching a football game.
Hyperbolic discounting provides a tool to quantify this concept of competing selves. Consider again the above image. The person you are between t1 and t2 makes choices differently than the You of all other times.
Another example, using this language of warfare between successive selves:
Looking at a day a month from now, I’d sooner feel awake and alive in the morning than stay up all night reading Wikipedia. But when that evening comes, it’s likely my preferences will reverse; the distance to the morning will be relatively greater, and so my happiness then will be discounted more strongly compared to my present enjoyment, and another groggy morning will await me. To my horror, my future self has different interests to my present self. Consider, too, the alcoholic who moves to a town in which alcohol is not sold, anticipating a change in desires and deliberately constraining their own future self.
Takeaways
Next Up: [Willpower As Preference Bundling]

